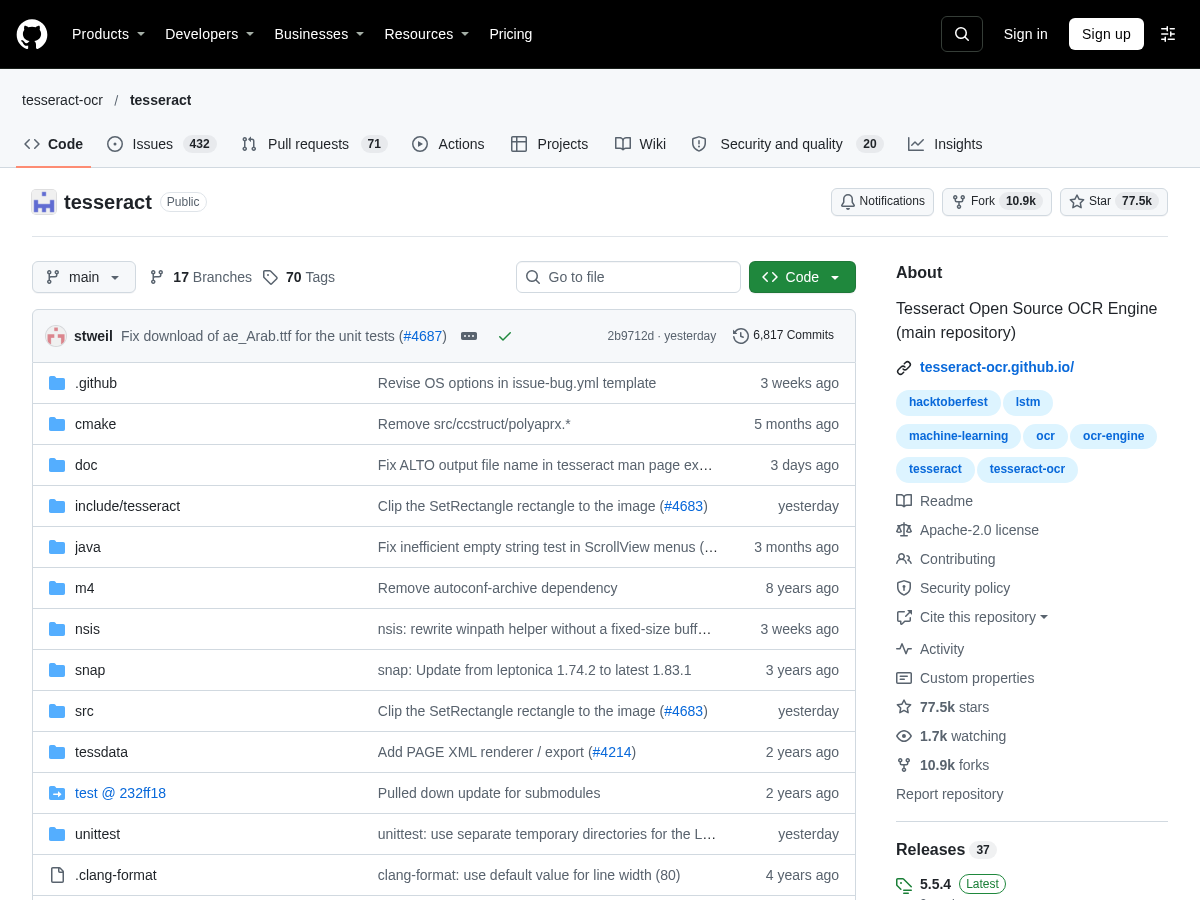
Tesseract is an open-source Optical Character Recognition (OCR) engine developed by Hewlett-Packard and now maintained by Google. It is capable of recognizing text in images and has support for over 100 languages. The engine uses a combination of machine learning algorithms and traditional computer vision techniques to achieve high accuracy. Tesseract can be used as a command-line tool or integrated into other applications through its API. It supports various input image formats, including PNG, JPEG, and TIFF, and can output text in several formats, including plain text, hOCR (HTML), PDF, and more. Tesseract is widely used in various applications, including document scanning, text extraction, and language translation. The project is actively maintained, with new versions and updates being released regularly. Tesseract has a large community of contributors and users, and its development is supported by Google. The engine is highly customizable, allowing users to train it to recognize specific languages or fonts. Tesseract is available under the Apache License, Version 2.0, and is free to use and distribute. The project's documentation is extensive, with a comprehensive user manual, FAQ, and API documentation available. Tesseract is a powerful tool for anyone looking to extract text from images, and its open-source nature makes it a popular choice among developers and researchers. The engine's high accuracy and flexibility make it suitable for a wide range of applications, from simple text extraction to complex document analysis. Overall, Tesseract is a robust and reliable OCR engine that is widely used in various industries and applications. Its open-source nature, high accuracy, and flexibility make it an ideal choice for anyone looking to extract text from images. Tesseract's development is ongoing, with new features and improvements being added regularly. The project's community is active, with many contributors and users participating in its development and providing support. Tesseract is a valuable resource for anyone looking to work with OCR technology, and its impact is evident in various fields, including document scanning, language translation, and text analysis.
Solves
Tesseract solves the problem of extracting text from images, which is a common challenge in various industries, including document scanning, text extraction, and language translation. The engine's high accuracy and flexibility make it suitable for a wide range of applications, from simple text extraction to complex document analysis. By using Tesseract, users can automate the process of extracting text from images, reducing the need for manual transcription and increasing productivity. Tesseract's ability to recognize text in images also enables various applications, such as document scanning, text extraction, and language translation, making it a valuable tool for anyone looking to work with OCR technology.